Skip to content
  • Categories
  • Recent
  • Tags
  • Popular
  • Users
  • Groups
Skins
  • Light
  • Brite
  • Cerulean
  • Cosmo
  • Flatly
  • Journal
  • Litera
  • Lumen
  • Lux
  • Materia
  • Minty
  • Morph
  • Pulse
  • Sandstone
  • Simplex
  • Sketchy
  • Spacelab
  • United
  • Yeti
  • Zephyr
  • Dark
  • Cyborg
  • Darkly
  • Quartz
  • Slate
  • Solar
  • Superhero
  • Vapor

  • Default (Flatly)
  • No Skin
Collapse
Brand Logo

NetXMS Forum

  1. Home
  2. Development
  3. message.c in libnetxms is right for east asian characters

message.c in libnetxms is right for east asian characters

Scheduled Pinned Locked Moved Development
19 Posts 2 Posters 110.3k Views
  • Oldest to Newest
  • Newest to Oldest
  • Most Votes
Reply
  • Reply as topic
Log in to reply
This topic has been deleted. Only users with topic management privileges can see it.
  • S
    S
    szll2010
    wrote on last edited by
    #1

    I found problems with displaying east asian characters in NETxms console, the following is the environment:

    1. Server on Windows (build with MBCS)
    2. Console on Windows (Build with Unicode)

    In this scenario, east asian character can be input, but after transfering to server, then the these characters was wrong in server's database. I read the source code, found that:

    1. In message.c file, GetVariableStr and SetVariable function's allocating memory is assume the MBCS is Single byte for one character, so it allocates double or half buffer for the converting, but the fact is not.
    2. In GetVariable Str, allocating memory for the pStr, but not found where to release the memory,  chance to leak ?

    Could you help to check the source file.

    1 Reply Last reply
    0
    • S
      S
      szll2010
      wrote on last edited by
      #2

      I patched the message.c file for the two functions, but still need you check the release of pStr:
      void *CSCPMessage::Set(DWORD dwVarId, BYTE bType, const void *pValue, DWORD dwSize)
      {
        DWORD dwIndex, dwLength, dwLenWC;
        CSCP_DF *pVar;
      #if !defined(UNICODE_UCS2) || !defined(UNICODE)
        UCS2CHAR *pBuffer;
      #endif

        // Create CSCP_DF structure
        switch(bType)
        {
            case CSCP_DT_INTEGER:
              pVar = (CSCP_DF *)malloc(12);
              pVar->df_int32 = *((const DWORD *)pValue);
              break;
            case CSCP_DT_INT16:
              pVar = (CSCP_DF *)malloc(8);
              pVar->df_int16 = *((const WORD *)pValue);
              break;
            case CSCP_DT_INT64:
              pVar = (CSCP_DF *)malloc(16);
              pVar->df_int64 = *((const QWORD *)pValue);
              break;
            case CSCP_DT_FLOAT:
              pVar = (CSCP_DF *)malloc(16);
              pVar->df_real = *((const double *)pValue);
              break;
            case CSCP_DT_STRING:
              dwLength = (DWORD)_tcslen((const TCHAR *)pValue);
              //pVar = (CSCP_DF *)malloc(12 + dwLength * 2);
              //pVar->df_string.dwLen = dwLength * 2;
      #ifdef UNICODE       
      #ifdef UNICODE_UCS2
               pVar = (CSCP_DF *)malloc(12 + dwLength * 2);
              pVar->df_string.dwLen = dwLength * 2;
              memcpy(pVar->df_string.szValue, pValue, pVar->df_string.dwLen);
      #else /* assume UNICODE_UCS4 */
               pVar = (CSCP_DF *)malloc(12 + dwLength * 2);
              pVar->df_string.dwLen = dwLength * 2;
              pBuffer = (UCS2CHAR *)malloc(dwLength * 2 + 2);
              ucs4_to_ucs2((WCHAR *)pValue, dwLength, pBuffer, dwLength + 1);
              memcpy(pVar->df_string.szValue, pBuffer, pVar->df_string.dwLen);
              free(pBuffer);
      #endif       
      #else /* not UNICODE */
               dwLenWC = mb_to_ucs2((const char *)pValue, dwLength, NULL, 0);
              pBuffer = (UCS2CHAR *)malloc(dwLenWC * 2 + 2);
              mb_to_ucs2((const char *)pValue, dwLength, pBuffer, dwLenWC + 1);
               pVar = (CSCP_DF *)malloc(12 + dwLenWC * 2);
               pVar->df_string.dwLen = dwLenWC* 2;
              memcpy(pVar->df_string.szValue, pBuffer, pVar->df_string.dwLen);
              free(pBuffer);
      #endif
              break;
            case CSCP_DT_BINARY:
              pVar = (CSCP_DF *)malloc(12 + dwSize);
              pVar->df_string.dwLen = dwSize;
              if ((pVar->df_string.dwLen > 0) && (pValue != NULL))
                  memcpy(pVar->df_string.szValue, pValue, pVar->df_string.dwLen);
              break;
            default:
              return NULL;  // Invalid data type, unable to handle
        }
        pVar->dwVarId = dwVarId;
        pVar->bType = bType;

        // Check if variable exists
        dwIndex = FindVariable(pVar->dwVarId);
        if (dwIndex == INVALID_INDEX) // Add new variable to list
        {
            m_ppVarList = (CSCP_DF **)realloc(m_ppVarList, sizeof(CSCP_DF *) * (m_dwNumVar + 1));
            m_ppVarList[m_dwNumVar] = pVar;
            m_dwNumVar++;
        }
        else  // Replace existing variable
        {
            free(m_ppVarList[dwIndex]);
            m_ppVarList[dwIndex] = pVar;
        }

        return (bType == CSCP_DT_INT16) ? ((void *)((BYTE *)pVar + 6)) : ((void *)((BYTE *)pVar + 8));
      }

      TCHAR *CSCPMessage::GetVariableStr(DWORD dwVarId, TCHAR *pszBuffer, DWORD dwBufSize)
      {
        void *pValue;
        TCHAR *pStr = NULL;
        DWORD dwLen, dwLenMB;

        if ((pszBuffer != NULL) && (dwBufSize == 0))
            return NULL;  // non-sense combination

        pValue = Get(dwVarId, CSCP_DT_STRING);
        if (pValue != NULL)
        {
            if (pszBuffer == NULL)
            {
      #if defined(UNICODE) && defined(UNICODE_UCS4)
              pStr = (TCHAR *)malloc(*((DWORD *)pValue) * 2 + 4);
               dwLen = (pszBuffer == NULL) ? (*((DWORD *)pValue) / 2) : min(*((DWORD *)pValue) / 2, dwBufSize - 1);
              ucs2_to_ucs4((UCS2CHAR *)((BYTE *)pValue + 4), dwLen, pStr, dwLen + 1);
              pStr[dwLen] = 0;
      #elif defined(UNICODE) && defined(UNICODE_UCS2)
              pStr = (TCHAR *)malloc(*((DWORD *)pValue) + 2);
               dwLen = (pszBuffer == NULL) ? (*((DWORD *)pValue) / 2) : min(*((DWORD *)pValue) / 2, dwBufSize - 1);
              memcpy(pStr, (BYTE *)pValue + 4, dwLen * 2);
              pStr[dwLen] = 0;
      #else
             
               dwLenMB = ucs2_to_mb((UCS2CHAR *)((BYTE *)pValue + 4), *((DWORD *)pValue) / 2, NULL, 0);
               pStr = (TCHAR *)malloc(dwLenMB  + 1);
               dwLen = (pszBuffer == NULL) ? dwLenMB : min(dwLenMB, dwBufSize - 1);
              ucs2_to_mb((UCS2CHAR *)((BYTE *)pValue + 4), *((DWORD *)pValue) / 2, pStr, dwLen + 1);
              pStr[dwLen] = 0;
      #endif
         
           
            }
            else
            {
              pStr = pszBuffer;
      #if defined(UNICODE) && defined(UNICODE_UCS4)
              dwLen = (pszBuffer == NULL) ? (*((DWORD *)pValue) / 2) : min(*((DWORD *)pValue) / 2, dwBufSize - 1);
               ucs2_to_ucs4((UCS2CHAR *)((BYTE *)pValue + 4), dwLen, pStr, dwLen + 1);
              pStr[dwLen] = 0;
      #elif defined(UNICODE) && defined(UNICODE_UCS2)
              dwLen = (pszBuffer == NULL) ? (*((DWORD *)pValue) / 2) : min(*((DWORD *)pValue) / 2, dwBufSize - 1);
              memcpy(pStr, (BYTE *)pValue + 4, dwLen * 2);
              pStr[dwLen] = 0;
      #else
             
               dwLenMB = ucs2_to_mb((UCS2CHAR *)((BYTE *)pValue + 4), *((DWORD *)pValue) / 2, NULL, 0);
               dwLen = (pszBuffer == NULL) ? dwLenMB : min(dwLenMB, dwBufSize - 1);
              ucs2_to_mb((UCS2CHAR *)((BYTE *)pValue + 4), *((DWORD *)pValue) / 2, pStr, dwLen + 1);
              pStr[dwLen] = 0;
      #endif

            }
        }
        else
        {
            if (pszBuffer != NULL)
            {
              pStr = pszBuffer;
              pStr[0] = 0;
            }
        }
        return pStr;
      }

      1 Reply Last reply
      0
      • V
        V
        Victor Kirhenshtein
        wrote on last edited by
        #3

        Hi!

        If you call GetVariableStr with only variable id argument, dynamically allocated string returned, and it is responsibility of the caller to deallocate it when it's no longer needed by calling "free".

        Best regards,
        Victor

        1 Reply Last reply
        0
        • V
          V
          Victor Kirhenshtein
          wrote on last edited by
          #4

          Hi!

          I have applied your patch, next release will have it. However, it will not solve all problems, because there are many places in server code where problems can occur if multibyte encoding is used. The only complete solution is to build server with unicode support. I've just finished converting server to unicode support - all 1.1.x versions will be built using unicode. I will not backport this to 1.0.x branch, as it is considered stable, and latest changes requires extensive testing. It will be great if you and other people from countries with non-latin alphabets can spend some time testing 1.1.x versions. I'll publish 1.1.0 installer on web site soon.

          Best regards,
          Victor

          P.S. Attached is a screenshot of console where Latin, Cyrillic, Japanese, and Arabic characters used simultaneously (and was successfully stored in database).
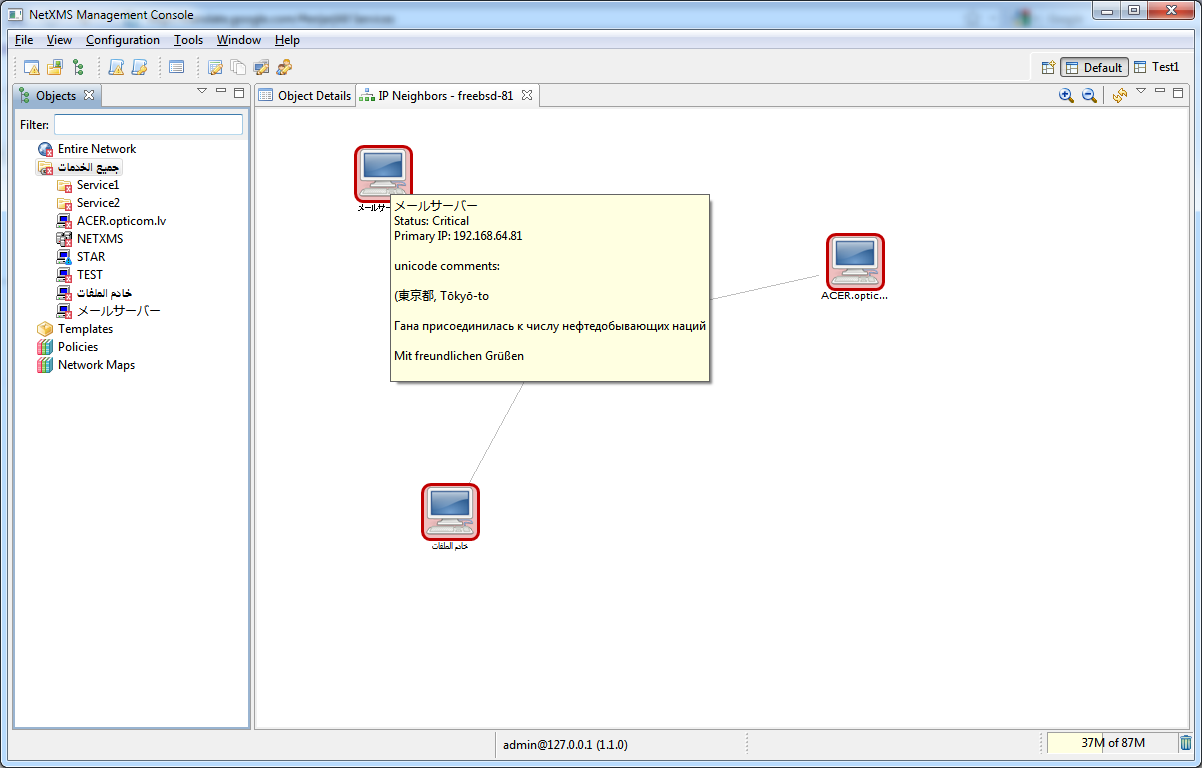

          unicode_console.png

          1 Reply Last reply
          0
          • S
            S
            szll2010
            wrote on last edited by
            #5

            Hi Victor,

            Thanks for your quick action.

            Is there any chance to port Agent to Unicode?

            1 Reply Last reply
            0
            • V
              V
              Victor Kirhenshtein
              wrote on last edited by
              #6

              Hi!

              Theoretically it is possible, but it will require a lot of work, because many places in agent code was written with usage of char instead of TCHAR, and because many system APIs on UNIX systems exist only in multi byte or event single byte form. I think that it can be relatively easy to convert Windows agent to unicode, and much harder to convert UNIX agent to unicode. Why you need unicode in agent?

              Best regards,
              Victor

              1 Reply Last reply
              0
              • S
                S
                szll2010
                wrote on last edited by
                #7

                Hi Victor,

                I try to manage some WIN CE devices. Not sure that MBCS is no problem. Could you advise?

                1 Reply Last reply
                0
                • V
                  V
                  Victor Kirhenshtein
                  wrote on last edited by
                  #8

                  So you are trying to build agent for WinCE? Then yes, you need to compile it in UNICODE, because WinCE lacks non-unicode versions of most API calls.

                  1 Reply Last reply
                  0
                  • S
                    S
                    szll2010
                    wrote on last edited by
                    #9

                    Hi Victor

                    Thanks. I noticed that some header files had been modified and I will try after the 1.1.0 is released.

                    And I want to know how to deal with the IP address changing problem. For example, some devices are  in remote site and connected through carrier network. The node's IP address is not the same as last time connected. Does the agent register and server recognizes the agent then change the node's ip address, or there is other solution?

                    1 Reply Last reply
                    0
                    • S
                      S
                      szll2010
                      wrote on last edited by
                      #10

                      Hi Victor,

                      Almost port the nxagentd to UNICODE for windows based the trunk version. Whether it is possible to port the dir relative structure members to TCHAR and dir.c to support TCHAR?

                      1 Reply Last reply
                      0
                      • V
                        V
                        Victor Kirhenshtein
                        wrote on last edited by
                        #11

                        Hi!

                        I think it should not be very hard. I'll try to create TCHAR version of opendir/readdir/closedir today. I'll notify you when they will be done.

                        Best regards,
                        Victor

                        1 Reply Last reply
                        0
                        • V
                          V
                          Victor Kirhenshtein
                          wrote on last edited by
                          #12

                          Wide version of opendir/readdir/closedir commited to trunk. Now you can use _TDIR, struct _tdirent, _topendir, _treaddir, _tclosedir.

                          Best regards,
                          Victor

                          1 Reply Last reply
                          0
                          • S
                            S
                            szll2010
                            wrote on last edited by
                            #13

                            Hi Victor,

                            Thanks for your port. Now the file system function works well.  I port the all the core agent and WINNT and winperf subagent to WINDOWS  UNICODE except the hddinfo has a bug.  Not really understand the  StrStrip function.

                            I also test the new config relative function, it can read ANSI and UNICODE content in the config file, but using the config->print function, it has problem with MBCS, like east asian characters. Could you check?

                            1 Reply Last reply
                            0
                            • V
                              V
                              Victor Kirhenshtein
                              wrote on last edited by
                              #14

                              Hi!

                              I don't understand what is the problem with Config::print. It uses wide character version of printf, so UNICODE build should print all characters correctly. Or you have problems with ANSI build?

                              Function StrStrip removes leading and trailing spaces and tabs from given string. It works in both ANSI and UNICODE builds. What exact problem you have?

                              Best regards,
                              Victor

                              1 Reply Last reply
                              0
                              • S
                                S
                                szll2010
                                wrote on last edited by
                                #15

                                Hi Victor,

                                I tested the new config API again but it does not work well with east asian characters.

                                The program is Unicode version, and the config's coding is UTF-8 and ANSI, in the config file there is some east asian characters. In  both scenarios,    the east asian characters became ?? under Config::print , the others are right.

                                Thanks

                                1 Reply Last reply
                                0
                                • S
                                  S
                                  szll2010
                                  wrote on last edited by
                                  #16

                                  Hi Victor,

                                  Sorry for mistake in the Config::print test using the setvbuf function to output. It should be OK.

                                  Best regards,

                                  1 Reply Last reply
                                  0
                                  • V
                                    V
                                    Victor Kirhenshtein
                                    wrote on last edited by
                                    #17

                                    Hi!

                                    Did you succeed with building UNICODE agent? If yes, it will be nice if you can share diff for converting agent to unicode - I then will be able to incorporate these changes to trunk and make unicode build as default option for Windows platform.

                                    Best regards,
                                    Victor

                                    1 Reply Last reply
                                    0
                                    • S
                                      S
                                      szll2010
                                      wrote on last edited by
                                      #18

                                      Hi Victor,

                                      I do send this port to the community.  For the reason of windows port, I erased some unix codes in the source and I trim the nxagentd.cpp to a simpler version. Two subagents were ported , WINNT and WINPERF.

                                      How to send the files to you?

                                      best regards,

                                      1 Reply Last reply
                                      0
                                      • V
                                        V
                                        Victor Kirhenshtein
                                        wrote on last edited by
                                        #19

                                        Hi!

                                        Send them to dump-at-netxms.org

                                        Best regards,
                                        Victor

                                        1 Reply Last reply
                                        0

                                        Hello! It looks like you're interested in this conversation, but you don't have an account yet.

                                        Getting fed up of having to scroll through the same posts each visit? When you register for an account, you'll always come back to exactly where you were before, and choose to be notified of new replies (either via email, or push notification). You'll also be able to save bookmarks and upvote posts to show your appreciation to other community members.

                                        With your input, this post could be even better 💗

                                        Register Login
                                        Reply
                                        • Reply as topic
                                        Log in to reply
                                        • Oldest to Newest
                                        • Newest to Oldest
                                        • Most Votes


                                        • Login

                                        • Don't have an account? Register

                                        • Login or register to search.
                                        Powered by NodeBB Contributors
                                        • First post
                                          Last post
                                        0
                                        • Categories
                                        • Recent
                                        • Tags
                                        • Popular
                                        • Users
                                        • Groups