Great! Thanks for your support and for pointing out the abort statement, very useful in these scenarios.
Best regards,
Kjell
Great! Thanks for your support and for pointing out the abort statement, very useful in these scenarios.
Best regards,
Kjell
Try "ip:8080/nxmc-2.0.3/" or rename nxmc-2.0.3.war to nxmc.war
The rename option is probably preferred, to keep URL consistent when upgrading to newer releases.
Just for your information...
Was upgrading from 1.2.17 to 2.0.3, but server segfaulted short after startup. Running under gdb gave that crashes took place in different parts of code from time to time, which was a bit confusing. But all seemed to be related to either loading DCI cache or applying templates.
In some template auto-apply scripts we use DCI values to determine if a template should be applied or not. As we know it takes some time before all DCI values are populated. In the old server this could cause nodes to be thrown out of templates at server start and then included again at next template-apply round. Problem we had with 2.0.3 was likely that we tried to reload cache for DCIs that just vanished because AutoApply removed them from nodes. This caused all kinds of null pointer crashes. Yes, this approach for applying templates may not be a recommended way, but in our case it is a neat way to distinguish between similar nodes but different versions that require different DCIs.
Our quick and dirty solution was to create the Apply template thread at a later point, and delay it a bit before it start working. Server then started as expected.
Hope this not has other unwanted side-effects.
~/netxms-2.0.3/src/server/core$ diff -u objects.cpp_orig objects.cpp
--- objects.cpp_orig    2016-04-10 12:46:07.272845568 +0200
+++ objects.cpp 2016-04-12 08:41:45.788328287 +0200
@@ -69,7 +69,12 @@
  */
 static THREAD_RESULT THREAD_CALL ApplyTemplateThread(void *pArg)
 {
-       DbgPrintf(1, _T("Apply template thread started"));
+   DbgPrintf(1, _T("Apply template thread started"));
+
+   DbgPrintf(2, _T("Delaying start of ApplyTemplateThread for 5min..."));
+   sleep(300);
+   DbgPrintf(2, _T("ApplyTemplateThread continuing."));
+
    while(1)
    {
       TEMPLATE_UPDATE_INFO *pInfo = (TEMPLATE_UPDATE_INFO *)g_pTemplateUpdateQueue->getOrBlock();
@@ -241,8 +246,8 @@
        // Initialize service checks
        SlmCheck::init();

-   // Start template update applying thread
-   ThreadCreate(ApplyTemplateThread, 0, NULL);
+   // Start template update applying thread, moved to end of LoadObjects
+   //ThreadCreate(ApplyTemplateThread, 0, NULL);
 }

 /**
@@ -1773,6 +1778,10 @@
    // Start map update thread
    ThreadCreate(MapUpdateThread, 0, NULL);

+   // Start template update applying thread. Moved from ObjectsInit
+   ThreadCreate(ApplyTemplateThread, 0, NULL);
+
+
    return TRUE;
 }
In transformation and threshold scripts, think you can simply use the "$1" to get last collected value.
dcival = $1;
If you wish to process values from another DCI you must of course use the FindDCI* methods, but here it looks like you are interested in the value from this particular DCI itself.
Best regards,
Kjell
Tried a dirty patch to icmp.cpp, which improved the situation a lot. Idea is to do a random delay before pinging, otherwise a lot of pings will be fired almost simultaneously.
--- icmp.cpp_bak        2014-11-28 09:23:44.559231668 +0100
+++ icmp.cpp    2014-11-28 09:28:48.212833890 +0100
@@ -227,8 +227,15 @@

    // Do ping
    nBytes = dwPacketSize - sizeof(IPHDR);
+   UINT32 seed = time(0) * dwAddr; // attempt to create different seeds for each call to each node
+   int iNumRetriesOrig = iNumRetries;
    while(iNumRetries--)
-   {
+   {  // random delay before start pinging
+      int min = 500 * (iNumRetriesOrig - iNumRetries+1); // min = 0 in first run, then wait longer and longer
+      int max = 1000 + min;  // increased random window between retries
+      int delay = min + (rand_r(&seed) % (int)(max - min + 1));
+      ThreadSleepMs(delay);
+
       dwRTT = 0;  // Round-trip time for current request
       request.m_icmpHdr.m_wId = ICMP_REQUEST_ID;
       request.m_icmpHdr.m_wSeq++;
@@ -364,7 +371,7 @@
 #endif
       }

-      ThreadSleepMs(500);     // Wait half a second before sending next packet
+      // ThreadSleepMs(500);     // Wait half a second before sending next packet // We do random delay in beginning of loop instead
    }

 stop_ping:
This feels like a workaround rather than a fix to the original problem, but it can at least help in pinpointing the problem. Looks like it is something outside NetXMS boundaries that doesn't keep up, like linux kernel, wmware hosts, network switches...
Worth to note that this installation contains a lot of nodes with neither netxms or snmp agents, guess this will cause a lot more icmp pinging during status polls than in installations with mostly agent-running nodes?
Could it be a limit on maximum allowed open file descriptors? I have seen this log message on server with many nodes, and increasing the FD:s helped. This server now reports (for root user)
# ulimit -n
8192
# ulimit -Hn
16384
# ulimit -Sn
8192
To increase (at least on debian), see /etc/security/limits.conf and pherhaps /etc/sysctl.conf.
My limits.conf includes
root            soft    nofile          8192
root            hard    nofile          16384
Regards,
Kjell
It is possible to check DCI values in template autoapply scripts.
In the generic template, create a DCI that collects the application version.
In the autoapply script of the version-specific template use something like this. (Not tested, may contain errors)
sub main() {
   ver = GetDCIValue($node, FindDCIByName($node, "AppVersion(theApp)"));
   // nxsl finally uses short-circuit evaluation :-)
   return (ver != NULL && $node->name ~= "node-name-regexp" && real(ver) > 1.2 && real(ver) < 2.0);
}
Hi, sorry for late reply.
Reverted to 1.2.6. No Syncer Thread problems, however some pollers still might get stuck. Have a feeling that this been the case in previous versions as well, but it is not a big problem.
For your question about number of nodes, output from nxadmc:
netxmsd: sh stat
Total number of objects:     5988
Number of monitored nodes:   1530
Number of collectable DCIs:  45318
Almost 900 nodes with agents, but not any large core routers/switches.
Best regards,
Kjell
Further investigations.... started a backup on a cold standby server. Now, the Syncer thread seems fine and no pollers stuck. But, when server is doing configuration polls, there is lot of Node down's and "Unable to create raw socket for ICMP protocol" in syslog. The Node down alarms will recover though, until next configuration poll cycle.
Ok, the usual file descriptor limit. ulimit -n shows 1024, increased and restarted server. No node downs, no errors in syslog, but... the stuck pollers and Syncer thread problem is back...
Reverted to 1024. Pollers/Syncer OK but lots of node downs. Now when the Syncer thread is alive, I will try to disable routing/topology polling on a bunch of nodes to see if I can get the best from these worlds.
Unfortunately it seems stuck. 9 hours now since last restart of netxmsd, and has been in Not responding state since. Besides from showing up in alarm browser, this is also logged to syslog. But no more occurrences since the initial one right after server start, so I'm quite sure that it been stuck all day.
Hi,
Recently updated to 1.2.7, but having an issue with Syncer Thread. A few minutes after server start, it stops responding and won't recover again.
Item Poller                                      20       Running
Syncer Thread                                    130      Not responding
Poll Manager                                     60       Running
nxadm command show pollers indicates that some pollers seems to be stuck, in particular topology pollers. Show queues gives that Topology poller has a large number, the other queues are fine.
Is is possible to completely disable topology polling at the server level?
Data collection and alarms seems to work. What is the impact of non-responding Syncer Thread? Any ideas on how to fix this?
Thanks in advance!
Hi!
I finally managed to build a static 1.2.1 agent, I did something like this:
$ ./configure --with-static-agent --with-all-static --with-static-subagents="" --with-internal-libexpat --with-internal-libtre --with-internal-zlib --prefix=/some/targetdir
$ make
Will complain, No target to build libnxdb exactly as you describe.
Build this by hand:
$ cd src/db/libnxdb/
$ make
Then try a build from source root again.
I then run into trouble when making nxpush, but that may be distribution specific (old debian).
Anyway, I disabled nxpush (don't need it)
$ <your favorite editor> src/agent/tools/Makefile
change
SUBDIRS = nxapush
to
SUBDIRS =
Then a make from source root dir should work.
Good luck!
Hi, thank you very much for your efforts!
But, I wonder if something still is broken?
Building on an old Debian etch (32-bit) with configuration
./configure --with-static-agent --with-all-static --with-static-subagents="pingcheck"
Configure script ok, but make complains:
../../../tools/create_ssa_list.sh "linux pingcheck" > static_subagents.cpp
  CXX    static_subagents.o
make[4]: *** No rule to make target `../../../src/db/libnxdb/libnxdb.la', needed by `nxagentd'.  Stop.
Also, seems to be some 64bit issues in RC1. When building on SuSE 64 bit, I get this:
  CXX    extagent.o
extagent.cpp: In function CSCPMessage* ReadMessageFromPipe(void*, void*):
extagent.cpp:131:34: error: cast from void to SOCKET loses precision
make[4]: *** [extagent.o] Error 1
Changed file include/nms_common.h, from int to intptr_t in the SOCKET typedef:
typedef intptr_t SOCKET;
Got a bit longer, next error was
push.cpp: In function void* PushConnector(void*):
push.cpp:245:63: error: cannot convert size_t* to socklen_t* for argument 3 to int accept(int, sock  addr*, socklen_t*)
make[4]: *** [push.o] Error 1
changed push.cpp,
 from: size_t size = sizeof(struct sockaddr_un);
 to: socklen_t size = sizeof(struct sockaddr_un);
Then a normal build is ok, but when building with
./configure --with-static-agent --with-all-static
it complains,
/usr/lib64/gcc/x86_64-suse-linux/4.5/../../../../x86_64-suse-linux/bin/ld: attempted static link of dynamic object `../../../src/db/libnxdb/.libs/libnxdb.so'
collect2: ld returned 1 exit status
I think I give up on this for now  Will try again when next release is out. Again, thanks for your support.
Just curious... is there a chance for a fix for this issue? No panic, otherwise I'll go for a "normal" build.
Thanks!
Hi!
I'm trying to build a static 1.2 agent,
./configure --with-static-agent
Configure script is happy, but make fails:
  CXX    snmpproxy.o
../../../tools/create_ssa_list.sh "linux ecs logwatch ping portcheck ups" > static_subagents.cpp
  CXX    static_subagents.o
  CXX    subagent.o
  CXX    sysinfo.o
  CXX    tools.o
  CXX    trap.o
  CXX    upgrade.o
  CXX    watchdog.o
make[4]: *** No rule to make target `../../../src/db/libnxdb/libnxdb.la', needed by `nxagentd'.  Stop.
Other configurations are building fine.
Any workarounds? Also, is there a way to control what subagents that are compiled in? (Trying to optimizing footprint for use in embedded devices )
Best regards.
Yes, now it works!
Looks great, thank you for efforts. Think a new web UI will be very appreciated.
Best regards.
Hi,
Good work with this new release!
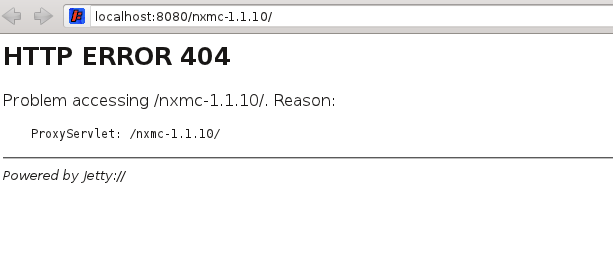
The new web interface was exciting news! But it didn't work for me, is it something I have missed?
I downloaded the war-file, and gave it to jetty. Jetty deployed it without any errors, but when I try to access it from the browser it get an error like this (see also attached screenshot):
Problem accessing /nxmc-1.1.10/. Reason:
ProxyServlet: /nxmc-1.1.10/
The application is there, if I use another non-valid url jetty gives another message. Suggestions..?
Regards,
Kjell
Hi!
I have not been able to find any retention settings for the alarms table, in the same way you can set retention for events (Server config). Am I missing something?
Otherwise, is it safe to manually delete old entries from alarms table? Are there some related tables that should be cleaned as well? Could deletion be done while the netxms server is running?
Postgres database, if that matters.
Table has grown quite large over time, and I would like to set up some archiving procedure.
netxms=# select count(*) from alarms;
count
--------
579673
(1 row)
Best regards,
Kjell
I see, then I misunderstood the purpose of Helpdesk state.
It would be nice to have the Acked/Outstanding info, so thanks for adding it in the next release. It would be very helpful to have it in the 1.0.13 too, but it's really up to you if you create a patch for it or not.
Many thanks,
Kjell
Yes, node info is now displayed! But "Helpdesk state as number" and "Helpdesk state as text" just shows as 0 and IGNORED (expected Acknowledged or Outstanding). Any quick fix available for this? Otherwise, we'll wait for the stable 1.1 branch and hope it works there
Best regards,
Kjell
nxalarm -u <user> -P <pass> -o "%h %H" <server> list
0 IGNORED
0 IGNORED
0 IGNORED
0 IGNORED
4 active alarms