
Hello,
for some purposes it would be beneficial to be able to change the address of a node via NXSL.
Maybe this function already exists, but I didn't find anything in the documentation.
Thanks
Andreas
Hello,
for some purposes it would be beneficial to be able to change the address of a node via NXSL.
Maybe this function already exists, but I didn't find anything in the documentation.
Thanks
Andreas
Hello,
It took me a while, but I was on holiday.
With the described procedure everything worked without problems, now the hypertable is also filled.
But I still have one question: how can I copy the logs in the background? Also with nxdbmgr or directly in the database?
Many thanks Filipp, really a great help
Andy
Hello Filipp,
Here is the requested data:
Timescale seems to be installed:
SELECT default_version, installed_version FROM pg_available_extensions where name = 'timescaledb';
 default_version | installed_version
-----------------+-------------------
 1.7.5           | 1.7.5
\d+ tdata_sc_default;
                                           Table "public.tdata_sc_default"
     Column      |           Type           | Collation | Nullable | Default | Storage  | Stats target | Description
-----------------+--------------------------+-----------+----------+---------+----------+--------------+-------------
 item_id         | integer                  |           | not null |         | plain    |              |
 tdata_timestamp | timestamp with time zone |           | not null |         | plain    |              |
 tdata_value     | text                     |           |          |         | extended |              |
Indexes:
    "tdata_sc_default_pkey" PRIMARY KEY, btree (item_id, tdata_timestamp)
    "tdata_sc_default_tdata_timestamp_idx" btree (tdata_timestamp DESC)
Hmm, so what could be the problem?
Thanks
Hello,
looks like I've got the next problem.
In the event log of the server I find the following entries:
Database query failed (Query: SELECT drop_chunks(to_timestamp(1628553600), 'tdata_sc_default'); Error: TS001 ERROR:  "tdata_sc_default" is not a hypertable or a continuous aggregate view
HINT:  It is only possible to drop chunks from a hypertable or continuous aggregate view)
I use, at least I thought I did, a TimescaleDB. During initialisation, it was also specified as such, and Timescale is also displayed as an extension in the database.
In timescaledb_information.hypertable, however, no tables are displayed, are these not used by Netxms?
If not, how can the old (or all) data be removed, the DB is currently over 500GB in size.
Thanks in advance
Andy
Hello and thank you for the reply.
Too bad, I was hoping to be able to use the whole thing without zoning.
Then I'll have to activate it and use it for this particular case.
Andy
Hello,
is it possible to have the query executed by another node?
Our server has no connection to the internet, but there is an agent which has the corresponding permissions.
I would like to query the web services from this agent, but I cannot find a suitable configuration.
"Poller Node" and/or "Source Node" do not seem to work here, we are not using zoning.
Checks via nxwsget are working as expected.
Thanks
Andy
Okay,
unfortunately, the server can no longer be started, even with default values.
Even when I load a dump on the test server and try it there, the server stops after a few minutes.
Is there a possibility to get support for this? We had planned to buy support for next year, maybe we can buy it earlier.
Thanks
Hello,
today the server crashed again for no apparent reason. The only explanation would be that a vMotion took place in ESX 30 minutes before.
Could this be the problem?
Thanks
Hi Victor,
I just uploaded an actual core-dump, name is "core_20210523".
Thanks
Hello everybody,
I have now tried several times to tune the server, but I can't get any further.
After some time, the service stops and restarts, so a practical use is not possible.
I now have a few core files, should I upload them?
Thanks
Hello,
is there anything new on this? I am also very interested in such a function.
Or is there another way to assign the appropriate rights?
Andi
Thanks Victor,
I will test the suggested values.
In fact, we have some adjustements in Hook::ConfigurationPoll. We set the interface expected state there depending on the name and CDP/LLDP. Is this a problem?
We also have a core network with large routing tables, but these are already deactivated. But it would be nice to be able to use them.
Core dump is not active yet, but I will switch it on. I can also try running the service with dbg to debug the crash.
Many thanks once again
Andi
Hello,
unfortunately, it took some time until I could deal with the topic again.
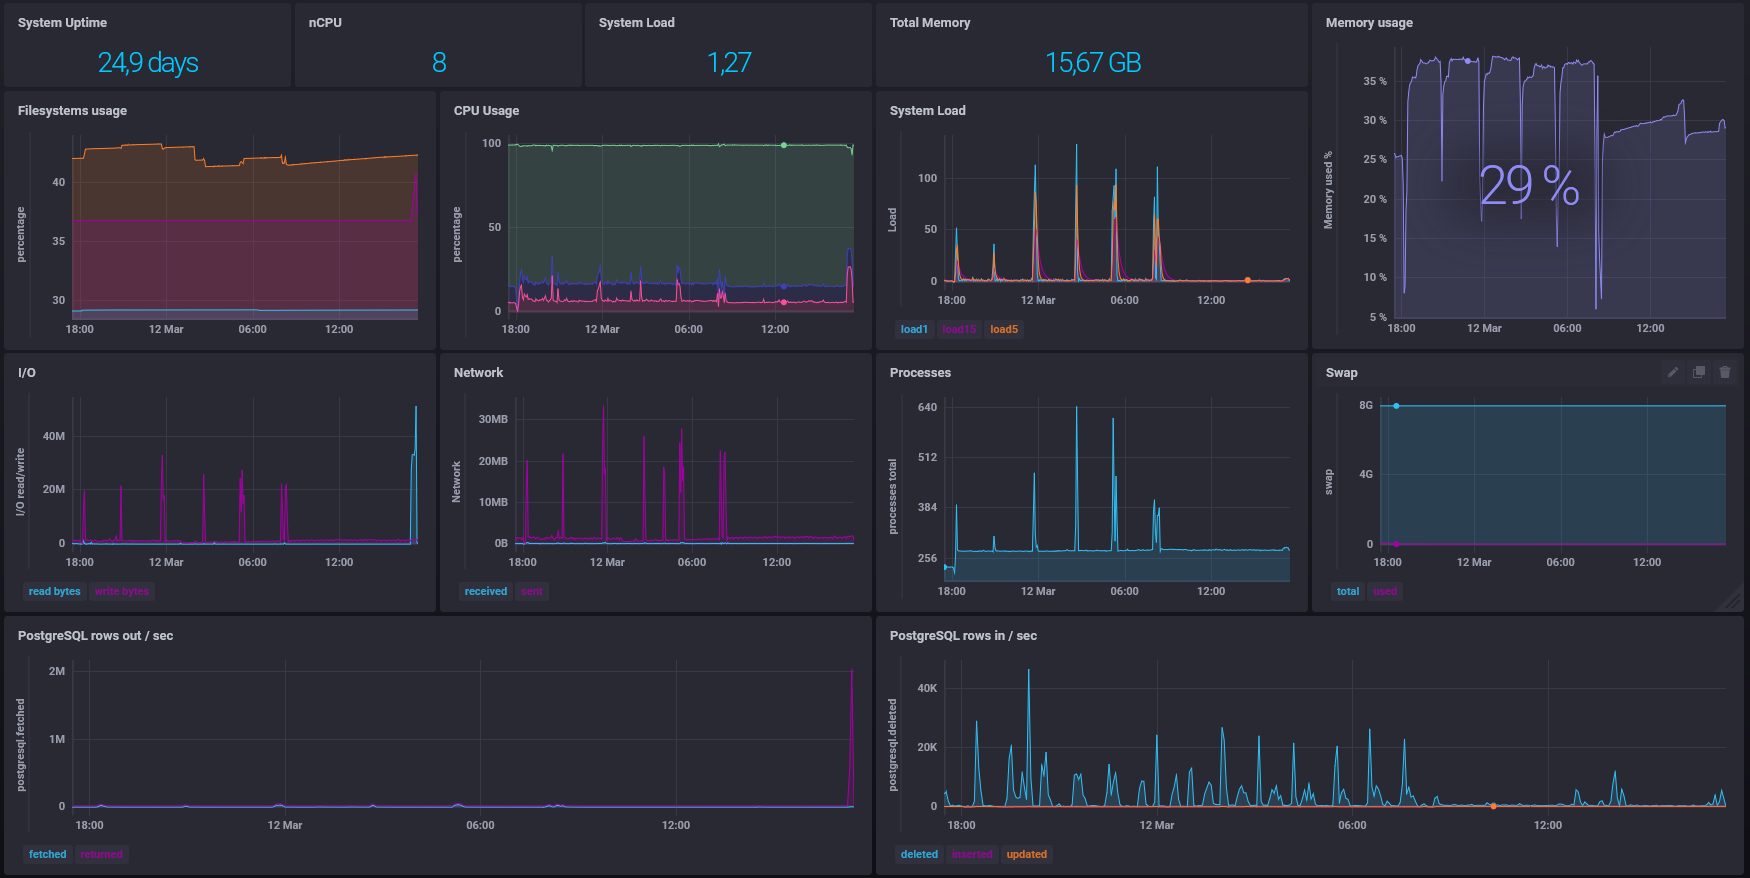
The memory usage looks OK to me, how do you recognise a slow database? At least I don't see anything in the associated logs.
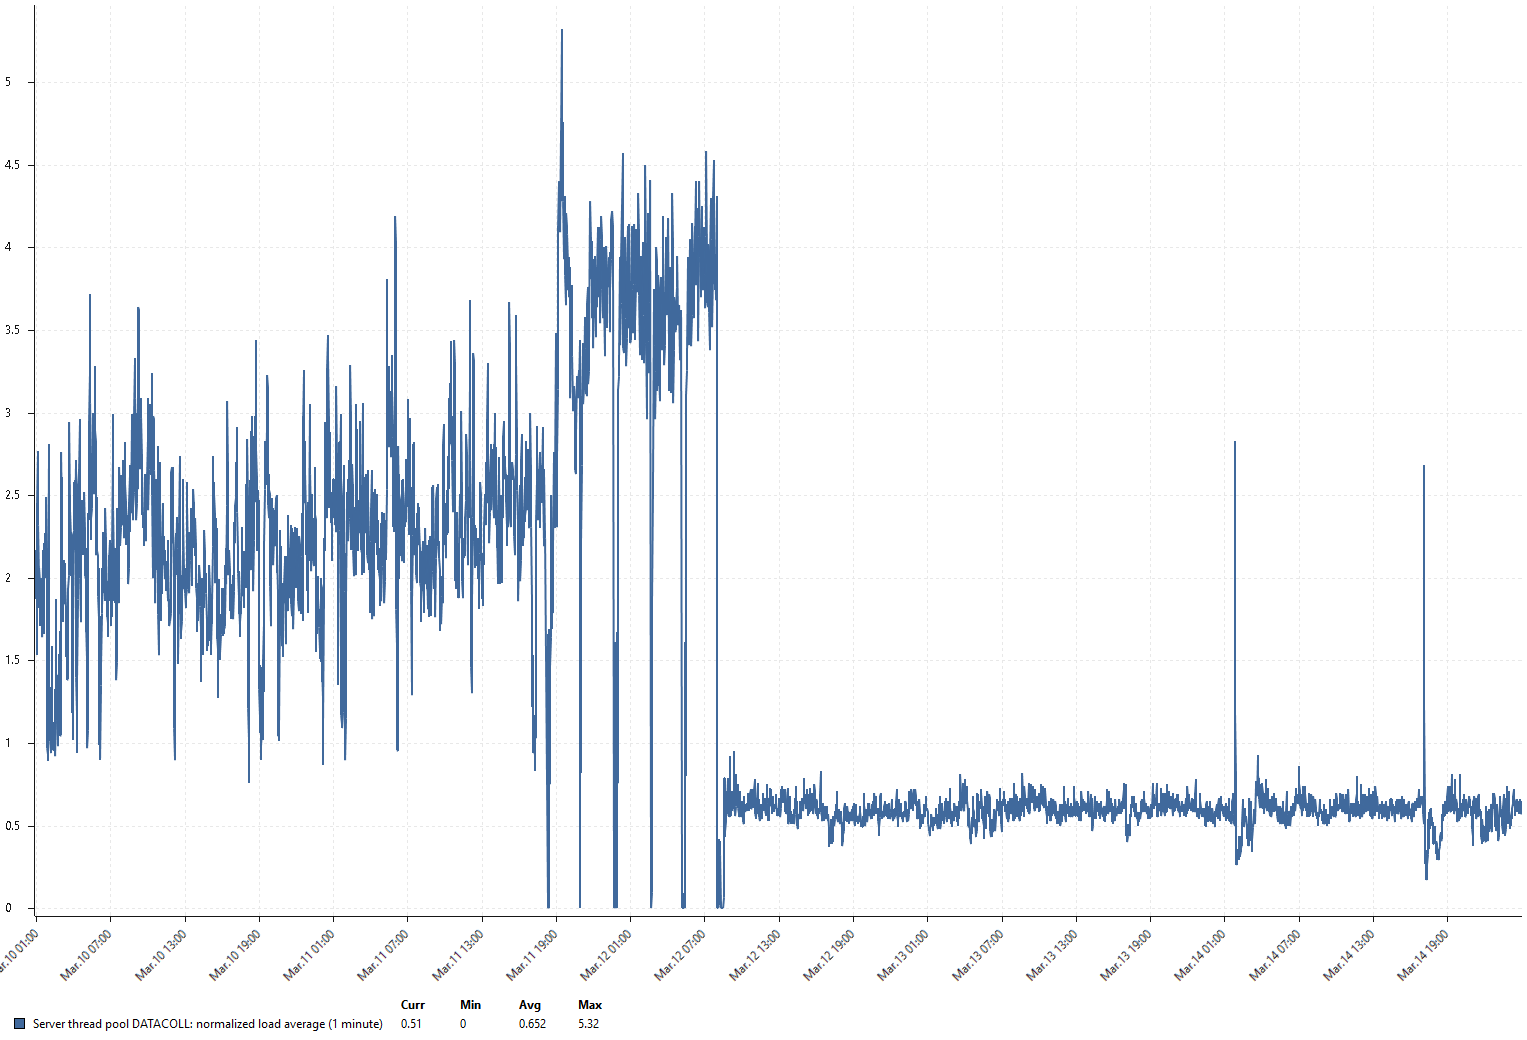
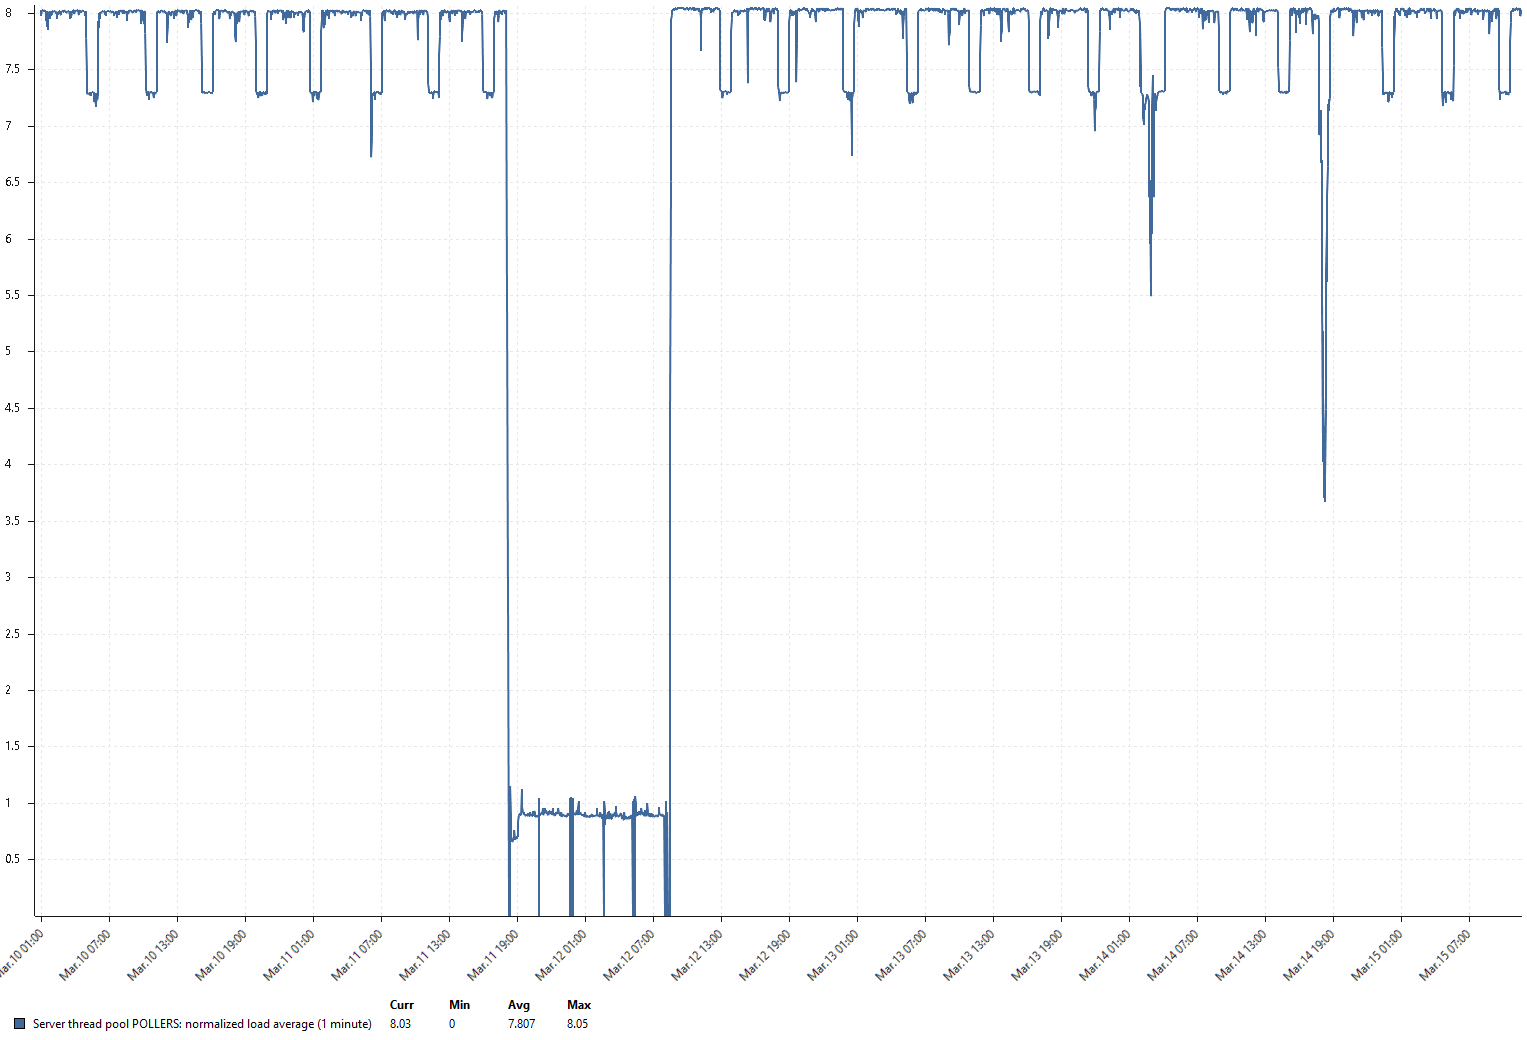
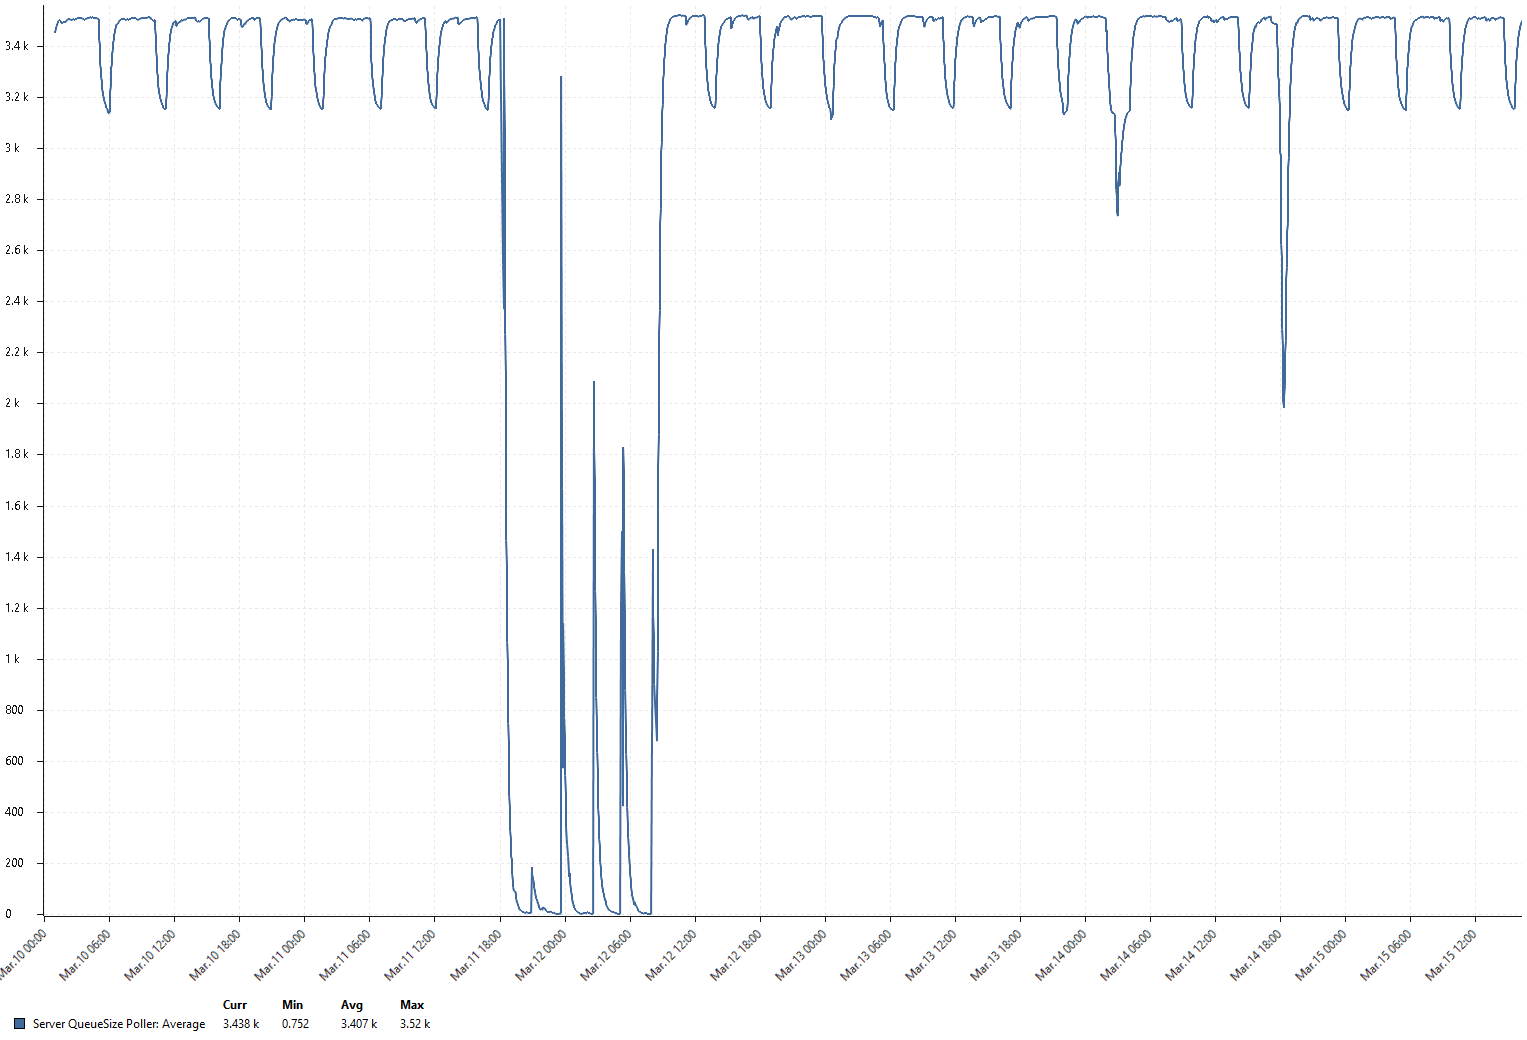
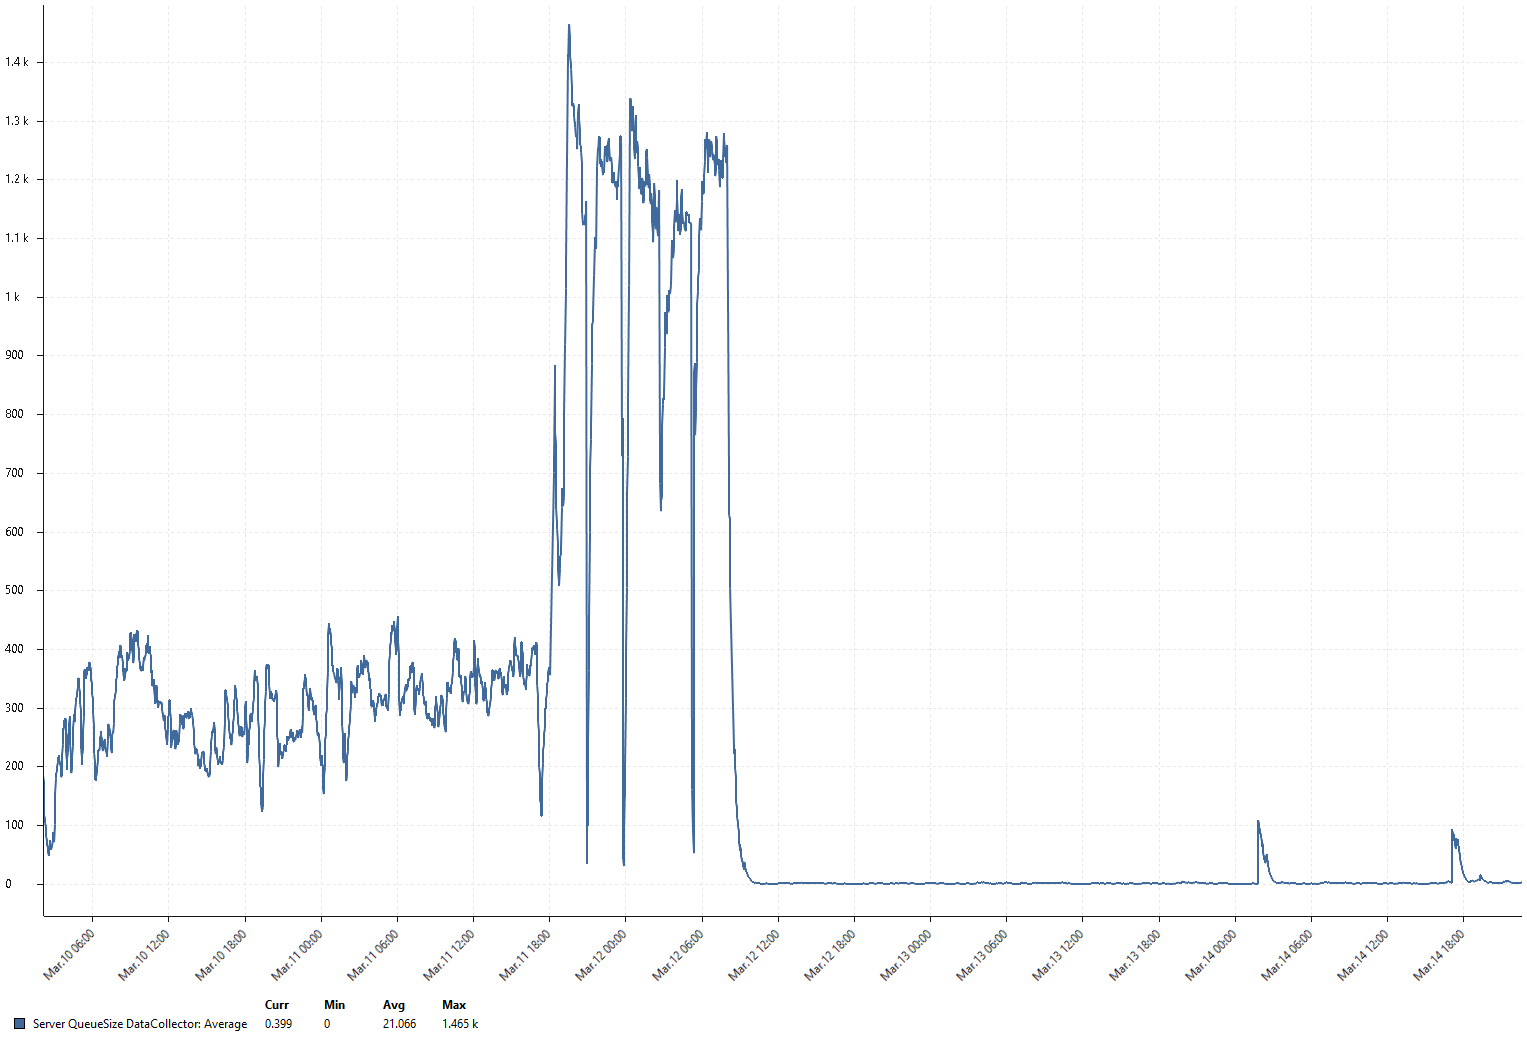
Attached are a few graphics, on 11 March at 18:00 I started the server with tuned values. During the night the service stops several times, but is restarted by corosync. In the morning of 12 March, I restore the default values.
Are there any values that I should look at more closely? Or which I should monitor before the next tuning attempt? Unfortunately, the tuning topic is described somewhat briefly in the documentation, and the designations no longer seem to be correct.
Andi
Hello,
I have a problem with the correct tuning of the server.
We use version 3.8.193 of the netxms-server, database is postgresql 11.11 with timescaledb.
The whole thing is set up as a cluster (2 nodes), as described here in the forum (pacemaker, corosync), under ESX.
Each VM has 8 CPUs and 16 GB RAM, storage (flash) is connected via SAN, the network has 10 Gbit.
Without (or moderate) tuning, the CPU-load is approx. 1,6.
However, the threads, mostly POLLERS, are completely overloaded:
POLLERS
   Threads.............. 500 (250/500)
   Load average......... 4006.09 4004.16 4002.81
   Current load......... 801%
   Usage................ 100%
   Active requests...... 4005
   Scheduled requests... 0
   Total requests....... 2991207
   Thread starts........ 250
   Thread stops......... 0
   Average wait time.... 13489521 ms
If I adjust the configuration, e.g. ThreadPool.Poller.MaxSize = 4000 and so on, the load is significantly reduced.
However, after some time (minutes, hours, days) the CPU-load increases to 300 or more and the service is terminated, systemctl says netxms-server aborted.
Here the stats:
Objects............: 39878
Monitored nodes....: 4050
Collectible DCIs...: 26354
Active alarms......: 970
Uptime.............: 27 days,  4:16:28
Approx. 1100 of these are network devices that are queried via SNMP. To reduce the load, the topology query is deactivated for these.
700 are server (with agent), the rest of the devices, with a few exceptions, are monitored via PING.
The network devices are polled via proxy, other devices are connected directly to the server.
I have returned to a working configuration (with slow pollers and data collection), but would like to know how I can optimise the system.
Unfortunately I don't have any logs from the last crash, is there any other information that helps to solve the problem?
I would appreciate any tips on how to make the system more reliable.
Andi
Hmm,
still no progress despite further investigations.
Executing the external action, this time without additional parameters, via nxaction works on Linux and Windows.
Action executed via EPP does not work on Linux and Windows, there are missing around 220 lines in the log of the agent.
So, is this a bug or am i calling the action wrong as stated above?
Andreas
Okay,
tried a few things and found following behaviour.
As mentioned above, executing action from CLI/CMD via nxaction on Agent (Windows) works from server (Windows and Linux).
Executing the action via EPP only works on Windows-Server, seems Linux-Server can't find the correct action.
Log-Files are attached, the first lines show command executed on server, followed by reaction on agent.
Thanks
Andreas
Hello,
forgot to reply to your answer.
With the new version at least the entry in the log-file seems correct, but executing the action is still not working.
Has someone a working example of executing a script via nxagent?
Thanks
Andreas
Hmm,
maybe related to the problem (or i'm too stupid to use parameters correctly).
If i execute a internal script via GUI's Server Console and pass multiple parameters, strings are split at blanks, even if enquoted by "".
Example: exec myScript 123 456 "Hello World"
So for this i get $1 = 123, $2 = 456, $3 = "Hello, $4 = World", i was expecting to get the complete string for $3.
Any thoughts on this?
Andreas
Hello,
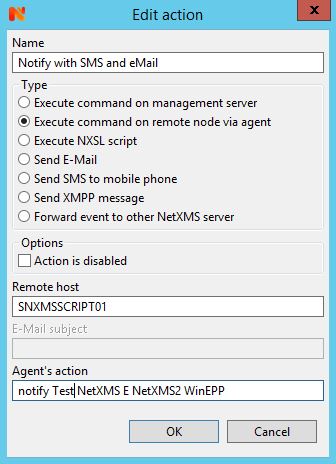
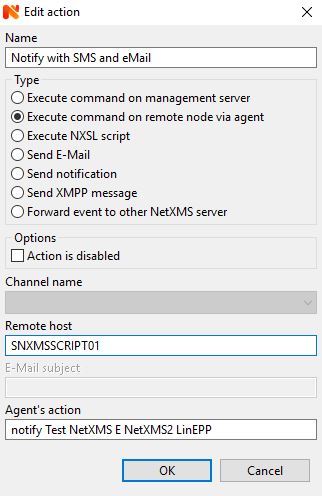
Configs are in the files attached, I there also tried to escape ("", '', \", \') the parameters.
Results stay the same, on Windows i get the correct parameter per string, on Linux the parameters are passed multiple times.
Thanks
Hi everyone,
I have a problem with executing an agent´s action via EPP and found also some strange behaviour on Linux, systems are:
What i want is to execute a cmd-Script (send message) on the Windows-Agent, tested it with following config (nxagentd.conf)
...
EnableActions = yes
Action = notify: C:\\Local\\Binw\\Notify_V3.cmd -S $1 -D $2 -M $3 -G $4 -L $5
...
Using parameters for the action, things get strange on the Linux-Server:
/bin/# ./nxaction -o 192.168.9.40 notify Test2 NetXMS E NetXMS2 LinNXACTION
Working, i get mail:
Executing action C:\\Local\\Binw\\Notify_V3.cmd -S Test -D NetXMS -M E -G NetXMS2 -L LinNXACTION of type 1
Via Action + EPP, not working:
Executing action C:\\Local\\Binw\\Notify_V3.cmd -S Test NetXMS E NetXMS2 LinEPP -D NetXMS E NetXMS2 LinEPP -M E NetXMS2 LinEPP -G NetXMS2 LinEPP -L LinEPP of type 1
I tried almost 50 different versions of the config (using " or ' around single parameters, all parameters, escaping the parameters with \" an \' and so on), but i always get a result like the above.
Seems there is an problem transmitting and escaping the string from Linux to Windows, because if i use same config from within Windows-Server i get (which is also not working):
Executing action C:\\Local\\Binw\\Notify_V3.cmd -S Test -D NetXMS -M E -G NetXMS2 -L WinEPP of type 1
So, is this a known problem or am i doing it wrong?
And, has someone a working example of using an action with multiple parameters?
Thanks
Andreas