Having such huge values which are not an accurate reflection throws out completely the ability to use the data. Given that the "events" are not being truly processed, probably more like a bug.
Would be nice to have some of these things ti be able to set as an exception, or have them report properly in the first place.
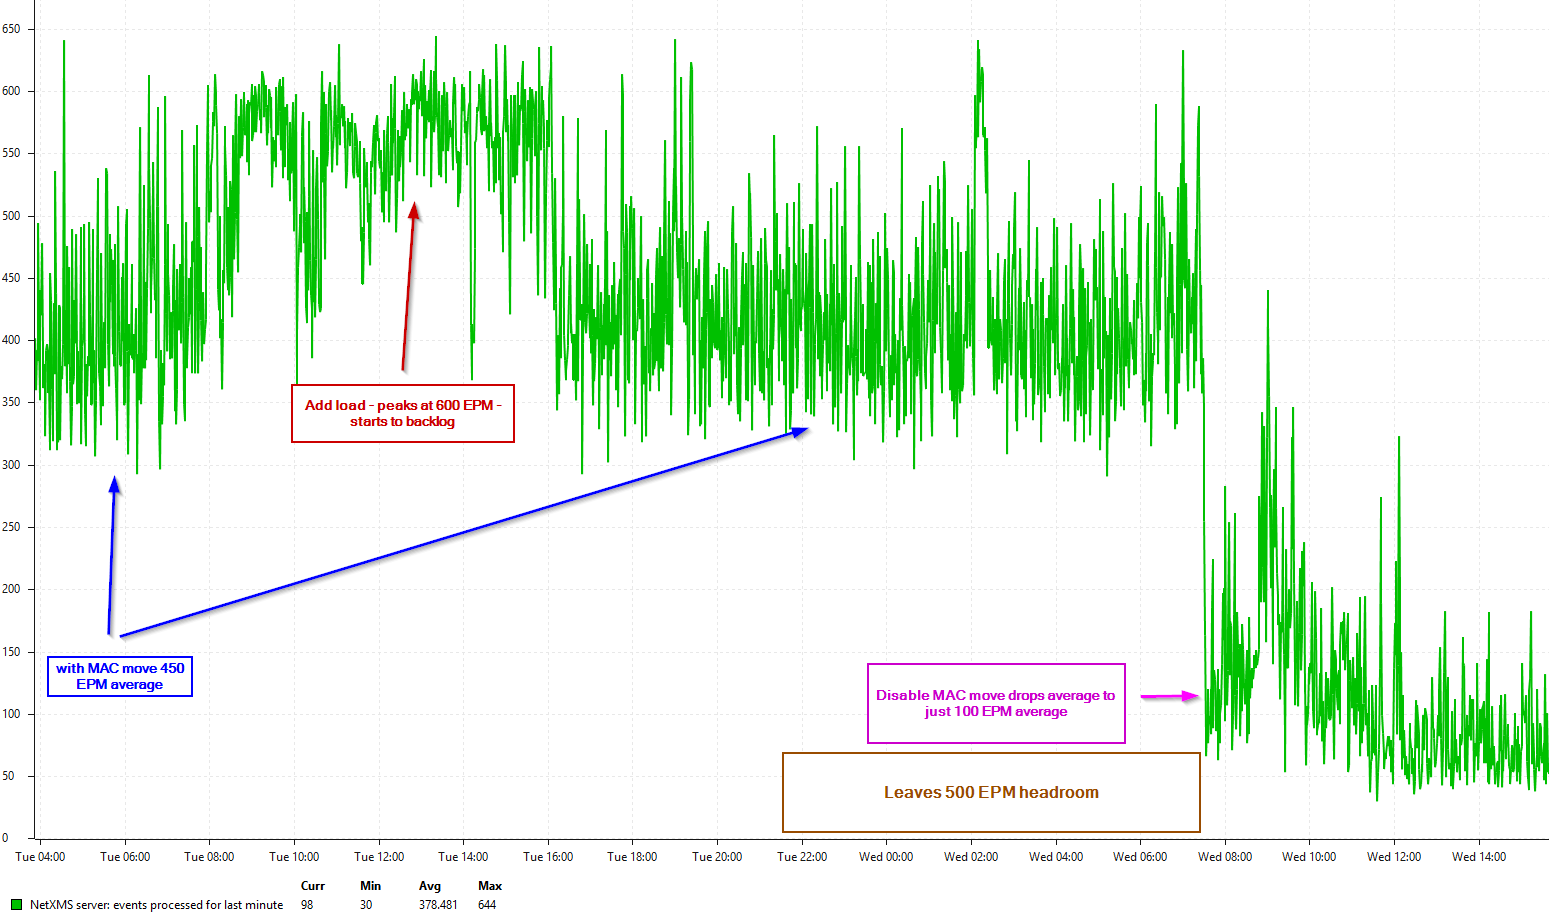
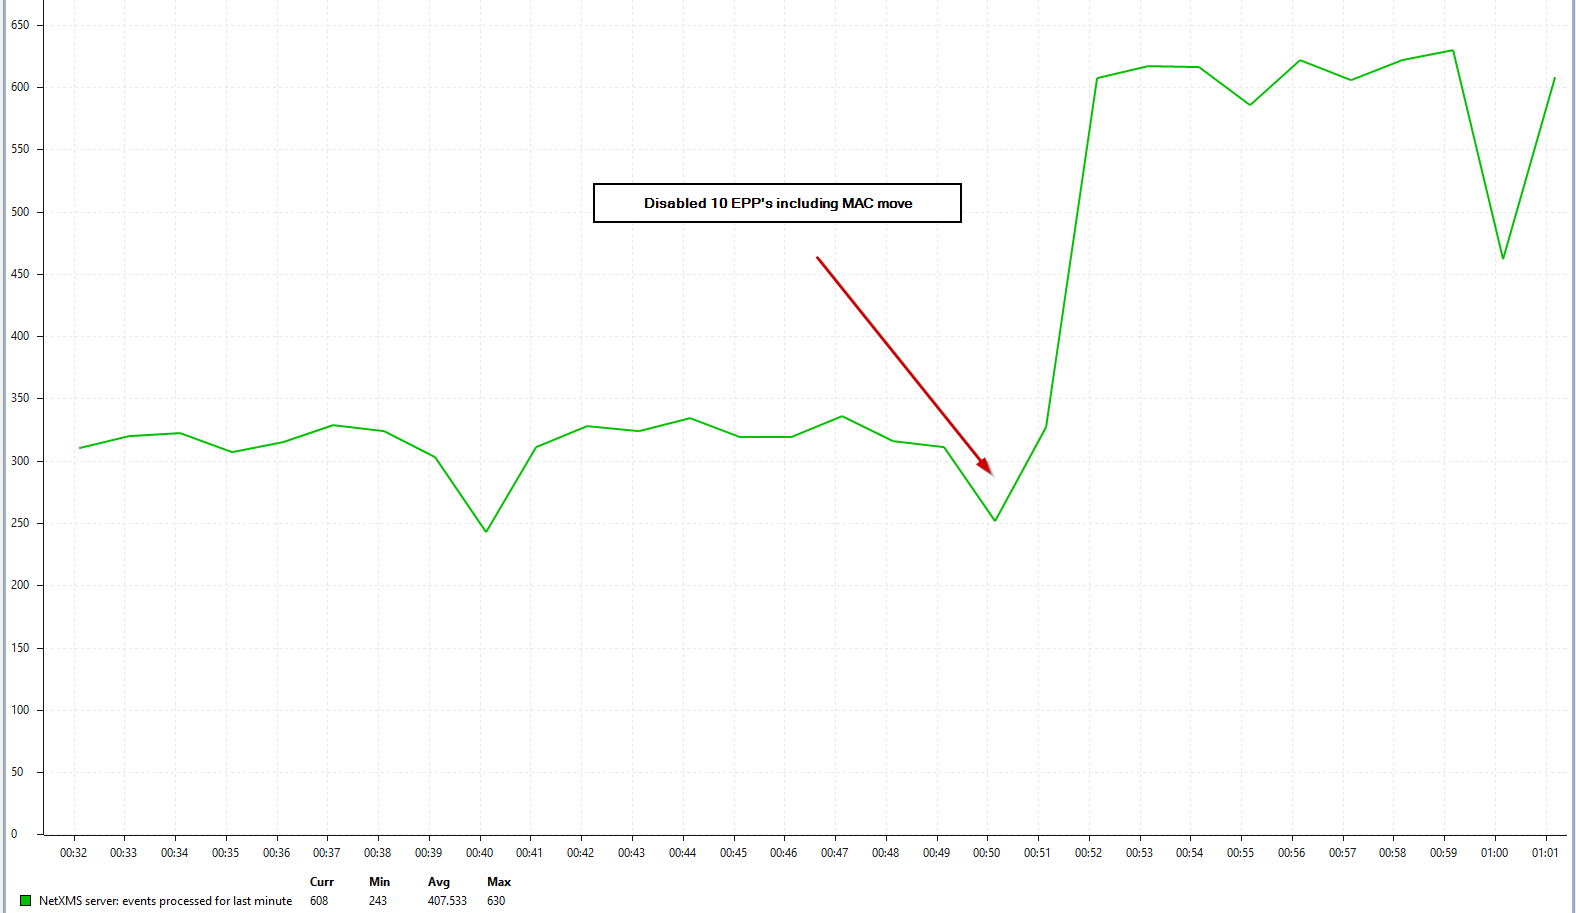
As for performance - headache continues  - more performance testing today, hitting our newer 600 EPM and backlog occurring. Good news though, having managed to get to 600 EPM through the Postgres settings, plus some EPP disabling, we caught up rather than triggering a bounce.
I have since disabled more EPP - down to 100 active - I can get the disabled events from Event log if I really need them. Not an ideal situation - but what options do I have - EVERYTHING else has been tried
On a positive note - my Network guys have agreed to stop the MAC move traps. On a negative note - they said they had done it - but traps keep coming. Will get that sorted tomorrow. 
Holistically speaking, Event Processor Queue needs to be a DCI item as being behind can be a calamity if a mission critical alarm was to be delayed by an hour. Faith in NetXMS is either there or it is not. If e cannot rely on alarms showing when the event comes in - what is the point of NetXMS? If we cannot even monitor when this is happening - how can we have faith?
I have an exception set for Events Processed in last minute of > 500 for last 4 polls; indicating NetXMS "might" be under stress. Having a monitor for Event Processor Queue > 1,000 would be much, much, much better.
Even nicer would be the capacity to process 1,000 events per minute AND have 200 EPP's.
My friendly Network guys made their change - what a difference it made!! Fixes my immediate problem - but NetXMS still needs better way of reporting when Event Processing starts banking up.